
Setting Up a Python Transcription API: A Working Guide
For most Python projects, the correct pattern is straightforward: call a hosted file-transcription SDK for batch jobs, and reach for a streaming SDK only when sub-second latency actually matters. Batch transcription tolerates network hiccups better and scales more predictably than realtime pipelines, according to OpenAI’s own transcription documentation. Reserve streaming for live captioning, voice agents, or call-center monitoring, where waiting for a completed file is not an option.
Here is the minimal path to a working transcript:
- Install the SDK with
pip. - Set your API key as an environment variable, never hardcoded.
- Open the audio file in binary mode.
- Call the transcription method with a model and language parameter.
- Print or parse the returned text.
Pro Tip: Test with a 30 second clip before running anything against a multi-hour recording. It surfaces auth and format errors in seconds instead of minutes.
If privacy is the constraint rather than latency, consider a local or offline model such as Faster-Whisper, which runs on your own hardware and avoids per-second billing entirely, though it shifts the cost to compute and typically trails hosted models on accuracy for noisy or accented audio. For diarization-heavy workloads, such as multi-speaker interviews or legal depositions, a model specifically benchmarked for speaker separation will outperform a generic transcription endpoint that treats diarization as an afterthought.
Key Takeaways
The most reliable Python transcription setup pairs a hosted file-transcription SDK for batch jobs with a streaming SDK reserved strictly for sub-second latency needs, backed by small-sample benchmarking before committing to a model.
| Point | Details |
|---|---|
| Match mode to latency need | Use batch file transcription by default; reserve streaming for live captioning or voice agents. |
| Let the SDK route file size | Small files typically go through sync calls; larger files route to async jobs automatically. |
| Preserve context across chunks | Use VAD-based splitting with a 1 to 2 second overlap window to avoid mid-sentence truncation. |
| Secure webhooks, not just polling | Validate signature headers and deduplicate by job ID to handle retried deliveries safely. |
| Benchmark before committing | OpenTranscription lets you compare 40+ models on cost, speed, and accuracy with per-second billing. |
Table of Contents
- Python Transcription API Quickstart: Install and Run Your First Call
- What File, Streaming, Sync, and Diarization Actually Mean in Code
- Copyable Python Code for Common Transcription Tasks
- Handling Long Recordings Without Losing Sentence Context
- Building Reliable Integrations at Scale
- Choosing the Right Model: Cost, Latency, and Accuracy Trade-offs
- Troubleshooting Common Python Transcription Errors
- Why Developers Compare Models Instead of Committing to One
- OpenTranscription Gives You One API and Real Benchmark Data
- What Engineers Get Wrong About Python Transcription APIs
- Sources
- FAQ
Python Transcription API Quickstart: Install and Run Your First Call
Getting from zero to a working transcript takes about five minutes if your environment is already set up correctly.
- Check your Python version. Most current SDKs, including Azure’s transcription client, require Python 3.9 or higher. Run
python3 --versionbefore anything else. - Install the client library. A typical install looks like
pip install openaiorpip install azure-ai-transcription, depending on the provider you choose. - Set your credentials as an environment variable. Never paste an API key directly into a script that might end up in version control. Use a pattern like:
export TRANSCRIBE_API_KEY="your-key-here"
- Write the minimal transcription call.
import os
from openai import OpenAI

client = OpenAI(api_key=os.environ["TRANSCRIBE_API_KEY"])

with open("audio.wav", "rb") as f:
    result = client.audio.transcriptions.create(
        file=f,
        model="gpt-transcribe",
        language="en"
    )

print(result.text)
The three parameters that matter most here are model (which engine transcribes the audio), language (skip it for auto-detection, but specifying it improves accuracy and speed), and an optional prompt argument that primes the model with domain vocabulary, useful for medical or legal terminology the model might otherwise mishear.
A detail that trips up a lot of developers: small local files usually route through a synchronous, blocking call that returns text directly, while larger files, remote URLs, or multipart uploads often get routed automatically into an async job queue by the SDK itself, as documented in transcribe-api’s routing behavior. You don’t have to manage this split yourself in most cases. The SDK detects file size and picks the right path.
- Sync calls: fine for files under roughly a minute or two.
- Async jobs: automatic for larger files, and required for true batch processing at scale.
What File, Streaming, Sync, and Diarization Actually Mean in Code
The terminology in transcription APIs sounds simple until you’re staring at a response object trying to figure out which field holds the speaker labels. Here’s what each term means for the code you write.
File (batch) transcription sends a complete audio file and waits for a complete transcript. Streaming (realtime) transcription sends audio in small chunks over a persistent connection, typically a WebSocket, and receives partial transcript events as speech is recognized, followed by a final event once a speech segment ends. Streaming requires you to manage audio buffers and handle network instability gracefully; batch processing sidesteps both problems, which is why practitioners default to batch unless latency requirements force otherwise.
Sync vs async describes how your code waits for results. A sync call blocks until the transcript is ready, fine for short clips. An async job returns a job ID immediately, and your code either polls for status or waits for a webhook callback once processing finishes.
Diarization assigns speaker labels (speaker_0, speaker_1, and so on) to segments of the transcript, paired with timestamps marking when each segment starts and ends. This is where response format choice matters:
text: plain transcript, no structure.verbose_json: includes timestamps and confidence scores per segment.diarized_json: adds speaker labels on top of timestamps.
On audio formats: most APIs accept WAV, MP3, M4A, and FLAC without complaint, but mono audio at a 16kHz, 16-bit sample rate remains the safest baseline for consistent accuracy across models, particularly for older or resource-constrained speech engines. Stereo files usually work too, but some diarization and channel-separation features specifically require stereo input with each speaker isolated on a separate channel, as Azure’s transcription client demonstrates.
Copyable Python Code for Common Transcription Tasks
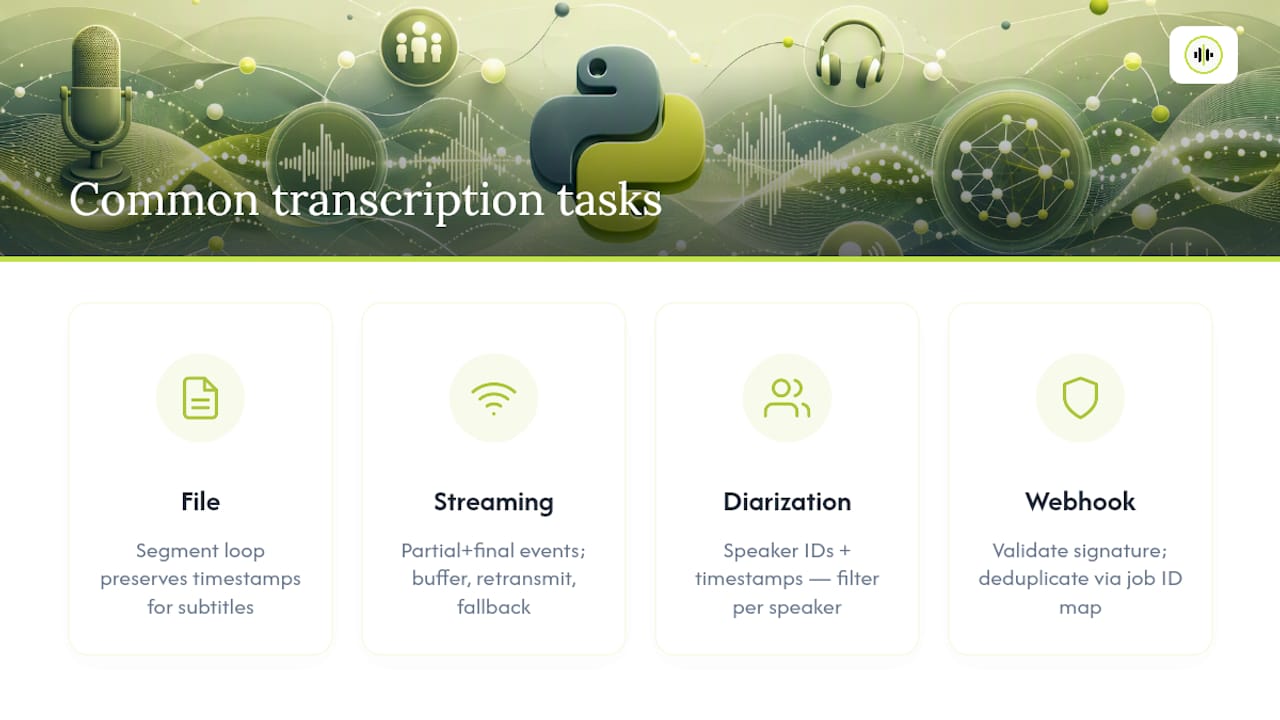
These four examples cover the tasks that come up in almost every transcription integration: uploading a file, handling a live stream, extracting speaker segments, and processing a webhook callback.
1. File transcription with confidence scores
import os
from openai import OpenAI

client = OpenAI(api_key=os.environ["TRANSCRIBE_API_KEY"])

with open("interview.wav", "rb") as f:
    result = client.audio.transcriptions.create(
        file=f,
        model="gpt-transcribe",
        languages=["en"],
        response_format="verbose_json"
    )

print(result.text)
for segment in result.segments:
    print(f"{segment.start:.1f}s - {segment.end:.1f}s: {segment.text} (confidence: {segment.confidence})")
This pattern works for any hosted file-transcription endpoint that supports verbose_json. The segment loop is what most developers actually need in production, since raw text alone loses timing information you’ll want for subtitle generation or searchable transcript indexes.
2. Streaming transcription with partial and final events
import asyncio
from openai import AsyncOpenAI

client = AsyncOpenAI(api_key=os.environ["TRANSCRIBE_API_KEY"])

async def stream_transcription(audio_stream):
    async with client.audio.transcriptions.stream(
        model="gpt-transcribe",
        language="en"
    ) as connection:
        async def send_audio():
            async for chunk in audio_stream:
                await connection.send(chunk)
            await connection.finish()

        asyncio.create_task(send_audio())

        async for event in connection:
            if event.type == "transcript.partial":
                print(f"Partial: {event.text}", end="\r")
            elif event.type == "transcript.final":
                print(f"
Final: {event.text}")
Streaming demands more careful engineering than the code above suggests. You need client-side audio buffering, retransmit logic for dropped chunks, and monitoring for partial transcript drift, where early partial guesses diverge noticeably from the eventual final text. Building a fallback path that reprocesses incomplete streaming segments as a batch job is worth the extra hour of engineering time.
3. Parsing diarized responses
with open("meeting.wav", "rb") as f:
    result = client.audio.transcriptions.create(
        file=f,
        model="gpt-transcribe",
        response_format="diarized_json"
    )

for segment in result.segments:
    speaker = segment.speaker
    start, end = segment.start, segment.end
    print(f"[{speaker}] {start:.1f}s-{end:.1f}s: {segment.text}")
Diarized JSON responses nest speaker identity alongside timestamp data, so a transcript of a three-person meeting becomes trivial to reformat into a readable dialogue, or to filter down to just one speaker’s contributions for compliance review.
4. Webhook handler for async jobs
from flask import Flask, request, abort
import hmac
import hashlib
import os

app = Flask(__name__)
WEBHOOK_SECRET = os.environ["WEBHOOK_SECRET"]

@app.route("/webhooks/transcription", methods=["POST"])
def handle_transcription_webhook():
    signature = request.headers.get("X-Signature", "")
    expected = hmac.new(
        WEBHOOK_SECRET.encode(),
        request.data,
        hashlib.sha256
    ).hexdigest()

    if not hmac.compare_digest(signature, expected):
        abort(401)

    payload = request.json
    job_id = payload["job_id"]
    transcript = payload["transcript"]["text"]

    save_transcript(job_id, transcript)
    return {"status": "received"}, 200
Validating the signature header before trusting the payload is not optional in production. Storing a canonical job ID mapping also lets you deduplicate safely when a webhook provider retries delivery, a known behavior that catches teams off guard the first time it happens.
Handling Long Recordings Without Losing Sentence Context
Every transcription provider caps request size somewhere, whether that’s a hard limit like 25 MB or an implicit ceiling tied to processing timeouts. If your provider doesn’t publish an explicit number, a safe default is chunking audio into 300 to 600 second segments, or better, splitting on voice activity detection (VAD) boundaries rather than fixed time intervals.
A reliable chunking workflow looks like this:
- Pre-split the audio using a VAD library to find natural pause points, not arbitrary timestamps.
- Upload each chunk as a separate async job rather than one giant sync request.
- Poll for job completion or, at scale, register a webhook per chunk.
- Merge the returned transcripts, adjusting timestamps by adding each chunk’s offset back in.
The biggest pitfall is splitting mid-sentence, which fragments context and can measurably hurt accuracy on the words nearest each cut point. Including a 1 to 2 second overlap window between adjacent chunks preserves that context and reduces truncation errors when reassembling the final transcript, a pattern OpenAI’s own guidance recommends for exactly this reason.
Pro Tip: When merging overlapping chunks, deduplicate the overlap region by matching the last few words of one chunk against the first few words of the next, rather than blindly concatenating both transcripts.
For files that already exceed your provider’s size limit before chunking, use direct multipart upload endpoints instead of the SDK’s default single-request method. Most SDKs handle this automatically once a file crosses their internal threshold, but knowing the manual path matters when you’re debugging a job that silently failed.
Building Reliable Integrations at Scale
Polling and webhooks solve the same problem, tracking async job completion, but they suit different situations. Polling works fine for small-scale projects or infrastructure without a public endpoint to receive callbacks. Webhooks are the better choice once you’re processing more than a handful of files a day, since they eliminate wasted requests and reduce latency between job completion and your system finding out about it.
- If polling, space requests at least 10 seconds apart and apply exponential backoff on errors. Many SDKs include a helper like
wait_for_completion()that handles this loop for you. - If using webhooks, validate every incoming signature before trusting the payload, and store a canonical job ID so retried deliveries don’t get processed twice.
- Wrap every network call in retry logic with backoff. Transient errors and rate limits are normal at scale, not exceptions to engineer around later.
- Make your job processing idempotent. If a webhook fires twice for the same job ID, the second call should be a no-op, not a duplicate database write.
Beyond error handling, track a few metrics from day one: confidence scores per transcript, error codes by category, job duration distributions, and a rough measure of transcript completeness against expected audio length. These numbers tell you when a model is degrading on a particular audio type long before a user complains about it.
Choosing the Right Model: Cost, Latency, and Accuracy Trade-offs
Picking a transcription model isn’t a one-time decision. It’s an ongoing trade-off between three metrics: word error rate (WER), latency, and cost per second of audio processed. Running a small benchmark, even 20 to 30 representative clips from your actual use case, beats trusting a vendor’s marketing claims, since accuracy varies significantly by accent, background noise, and domain vocabulary. Benchmarking a representative sample before committing to a model in production is worth the half day it takes.
- Hosted high-accuracy models generally win on transcription quality but cost more per second and require sending audio off-device.
- Local or offline models like Faster-Whisper avoid per-minute API costs and keep audio on your own infrastructure, a meaningful advantage for healthcare or legal audio, but they demand GPU or CPU resources you have to provision and maintain yourself.
- Streaming models trade some accuracy for the sub-second latency that live use cases require; batch models optimize for accuracy and cost efficiency instead.
Domain adaptation matters more than most teams expect. Passing a prompt parameter with domain-specific vocabulary, or supplying a keyword list for product names and acronyms, can measurably reduce misrecognitions in specialized fields like medicine or finance. For multilingual projects, automatic language detection works well for clearly spoken, single-language audio, but accuracy drops on code-switched speech or heavy accents, so specifying the language explicitly whenever you know it in advance remains the safer default.
Troubleshooting Common Python Transcription Errors
Most transcription failures fall into a short list of repeat offenders, and a quick pre-deployment pass through this checklist saves debugging time later.
- Audio preprocessing: normalize the sample rate to 16kHz where possible, convert stereo to mono unless you specifically need channel separation for diarization, and check for clipping or silence at the start of the file.
- Authentication errors: confirm the environment variable is actually loaded (
print(os.environ.get("TRANSCRIBE_API_KEY"))during debugging), check that your token has the correct scopes, and verify the credential hasn’t expired, a common issue with Azure AD tokens specifically. - Timeouts and partial transcripts: if a job returns less text than the audio length suggests, check job status codes for partial-completion flags and re-request the missing segment rather than assuming the whole file failed.
- Security: store API keys in a secrets manager or environment variable injection system, never in source code, and rotate webhook signing secrets on a regular schedule.
Pro Tip: Log the audio duration alongside the returned transcript length. A sudden mismatch between the two is often the earliest signal that a job partially failed silently.
Why Developers Compare Models Instead of Committing to One
Most transcription integrations start with a single provider and stay there by default, not because it’s the best fit, but because switching feels like extra work. That default has a real cost: word error rates and pricing per second vary enough across models that picking blind can mean overpaying or under-performing on accuracy for months.
OpenTranscription addresses this by giving Python developers a single API that routes to more than 40 transcription models, with live benchmarking across cost, speed, and accuracy so you can pick per project rather than committing once. The platform supports real-time streaming, speaker diarization, and over 105 languages, and every transcript comes back structured with word-level timestamps and confidence scores, the same fields the code examples above parse directly.
- Model selection by measured performance, not vendor claims.
- Per-second billing with no subscription commitment.
- One integration surface instead of separate SDKs for every provider you want to test.
This maps directly onto the pain points covered above: model selection headaches, pricing opacity, and the engineering overhead of maintaining multiple provider integrations just to compare accuracy.
OpenTranscription Gives You One API and Real Benchmark Data
If you’ve been weighing a single hosted SDK against building your own model comparison layer, OpenTranscription removes that trade-off entirely. It’s the alternative to locking into one provider’s SDK and hoping the accuracy holds up for your specific audio.
Instead of committing to one model’s word error rate and pricing structure sight unseen, you get live rankings across 40 plus benchmarked models before you write a single line of production code. The model catalog lists language support, diarization capability, and timestamp precision per model, so you can match a model to your exact use case, whether that’s multilingual customer support calls or single-speaker podcast transcription. For latency-sensitive projects, the realtime rankings narrow the field to models that actually hold up under streaming conditions. Pricing runs per second processed, with no subscription tier to commit to before you know your actual usage. Start by running your own representative audio sample through the model comparison tool and see which model wins on your accuracy, latency, and cost priorities before you build against just one.
What Engineers Get Wrong About Python Transcription APIs
The conventional advice treats transcription API selection as a one-time architecture decision: pick a provider, write the integration, move on. That’s backwards. Word error rates shift between model versions, pricing structures change, and the model that handled your English podcast audio well might struggle badly on a multilingual support call six months later. Treating model choice as a fixed decision rather than an ongoing benchmarking practice is the single biggest gap between how teams build transcription pipelines and how they should.
The second underrated point: most teams over-invest in streaming infrastructure they don’t need. Streaming sounds more impressive, but it demands buffer management, jitter handling, and fallback logic that batch processing sidesteps entirely. Unless your product genuinely requires sub-second response, and few do outside live captioning or voice agents, batch transcription with a good chunking strategy will get you to production faster and with fewer 3 AM pages.
What should come first, before writing a single line of integration code, is running a real benchmark against your actual audio. Vendor accuracy claims rarely reflect your specific noise profile, accent mix, or vocabulary.
— Benjamin
Sources
- File transcription | OpenAI API
- azure-ai-transcription · PyPI
- How to Use Speech Recognition in Python (Real Python)
FAQ
What Is the Best Transcription API for Python Projects?
There isn’t one universal best answer, since accuracy and cost vary by audio type and language. The most practical approach is benchmarking a few models against your specific use case using a comparison tool like OpenTranscription’s ranking system rather than trusting a single vendor’s claims.
How Can I Use Python to Transcribe Speech?
Install a transcription SDK with pip, set your API key as an environment variable, open your audio file in binary mode, and call the transcription method with a model and language parameter, as shown in the quickstart example above. For prototyping across multiple engines, SpeechRecognition offers a simpler entry point before moving to a production SDK.
Which API Is Best for Python Speech Recognition?
For production use, a direct hosted SDK like OpenAI’s transcription API or Azure’s transcription client gives finer control over diarization, timestamps, and confidence scores than wrapper libraries. Wrapper libraries like SpeechRecognition remain useful for quick prototyping but often lack the production-grade tuning production systems need.
What API Can I Use to Get YouTube Transcripts?
YouTube’s own caption data can sometimes be pulled through third-party libraries, but for audio you extract yourself, any file-transcription API, hosted or via a benchmarking platform like OpenTranscription, works by uploading the extracted audio track directly for transcription.
Do I Need Streaming Transcription for a Realtime App?
Only if your application genuinely requires sub-second response, such as live captioning or a voice agent. Batch transcription is simpler to build, more resilient to network issues, and sufficient for the majority of transcription use cases.