
Skip Reencode: Transcribe Opus Audio for Developers With 40+ Models
Yes, OPUS files transcribe directly on modern automatic speech recognition systems without conversion. For a single quick file, an online OPUS-aware AI transcriber gets you text in minutes. For privacy, volume, or automation needs, a local pipeline or an API platform like OpenTranscription.io gives you more control over model selection, diarization, and cost per second of audio.
TL;DR:
- Transcribing Opus files directly without conversion is possible for both online tools and local pipelines, but container mismatches may cause rejection errors.
- Re-muxing with ffmpeg using the
-c copyflag or changing the file extension often fixes unsupported file issues caused by container differences.- Ideal Opus bitrate for accurate transcription is at or above 64 kbps mono; lower bitrates, especially around 24 kbps, increase the likelihood of transcription errors.
- The choice of export format should match the intended downstream use, with JSON preferred for structured data and confidence scores to streamline proofreading.
- Benchmarking multiple speech-to-text models with platforms like OpenTranscription improves accuracy, speed, and cost efficiency, especially at higher audio volumes.
Table of Contents
- How Does Opus Audio Transcription Work Step by Step?
- Why Do Some Tools Reject .opus Files?
- Does OPUS Bitrate Actually Affect Transcription Accuracy?
- Which Export Format Should You Choose for Opus Transcripts?
- How Do You Choose the Right Transcription Workflow?
- How Do You Build a Local OPUS Transcription Pipeline?
- What People Get Wrong About Transcribing Opus Audio
- Get Opus Transcription Right the First Time With OpenTranscription
- Sources
- FAQ
How Does Opus Audio Transcription Work Step by Step?
Opus audio transcription follows one of two paths depending on whether you need a one-off result or a repeatable process. Online tools handle single files with minimal setup; local or API-based pipelines suit anyone processing volume or requiring data control.
For a browser-based online transcriber, the sequence is nearly identical across services:
- Select the source language (auto-detect works for most modern models, but manual selection reduces errors on accented speech).
- Upload the OPUS file directly, no conversion needed in most cases.
- Enable speaker labeling if the recording involves more than one voice.
- Run the transcription and let the model process the audio.
- Review the output against the audio, paying attention to flagged low-confidence segments.
- Download in your preferred format.
Local or API-based workflows follow a similar logic with more technical control:
- Re-mux the file if the tool rejects the raw
.opusextension (covered in detail below). - Point a local ASR model or an API endpoint at the file.
- Export in the format your downstream process expects, whether that’s a subtitle file or structured JSON.
Processing speed on most online tools runs at several times real-time. According to VexaScribe’s testing, a one to three minute voice note often finishes in 30 to 90 seconds. Free tiers typically cap file length or monthly minutes, so check limits before batching long recordings.
Why Do Some Tools Reject .opus Files?
OPUS is a codec, not a container, and that distinction causes most of the “unsupported file” errors people hit. The audio data itself can be wrapped in different containers: a standalone .opus file, or an OGG container holding an Opus stream, commonly seen as .ogg. Some transcription tools only whitelist certain extensions, so a perfectly valid Opus-in-ogg file gets rejected simply because its wrapper doesn’t match what the parser expects.
This is exactly what happens with voice notes exported from messaging apps. WhatsApp on Android, for instance, commonly saves voice messages as Opus-in-ogg containers around 24 kbps, while Discord voice clips can arrive as raw .opus. Renaming the extension sometimes works, but the more reliable fix is a container swap using ffmpeg.
- Try renaming
.opusto.ogg(or vice versa) as the fastest test. - If renaming fails, re-mux with ffmpeg using the
-c copyflag, which changes the container without re-encoding the audio streams, according to ffmpeg’s own documentation. - Avoid re-encoding unless you specifically need to change the bitrate, since it adds processing time and can degrade already-compressed voice audio.
Pro Tip: Keep a copy of the original file before re-muxing. Container swaps are lossless, but it’s good practice to preserve the source in case a tool later needs the original wrapper.
Does OPUS Bitrate Actually Affect Transcription Accuracy?
Bitrate matters more than most people assume when compression gets aggressive. OPUS was built for efficient voice compression, and it performs well down to surprisingly low bitrates, but accuracy on automated transcription degrades once you drop below a certain threshold.
The accuracy cliff: Cloudinary’s codec guidance recommends 64 kbps mono as a practical target for reliable ASR results, and warns that accuracy drops significantly under roughly 24 to 32 kbps.
That threshold matters in practice because a huge share of the OPUS audio people need transcribed comes from messaging apps recording well below the ideal range. WhatsApp Android voice notes commonly sit near 24 kbps, which explains why these files tend to produce more transcription errors, particularly around proper nouns and overlapping speech.
A few recording habits make a measurable difference before you ever hit “transcribe”:
- Record in a quiet room; background noise compounds compression artifacts.
- Keep the microphone close to the speaker rather than relying on a phone’s built-in mic across a room.
- Use a sample rate of at least 16 kHz for voice, higher if the source allows it.
- Where possible, capture in WAV or another lossless format and compress to OPUS afterward rather than recording directly at a low bitrate.
Which Export Format Should You Choose for Opus Transcripts?
The right output format depends entirely on what happens to the text after transcription, not on the source audio itself. A plain TXT file suits quick reference or archiving. DOCX works better when someone needs to edit or format the transcript for a report. SRT or VTT are the standard for subtitles and closed captions. JSON, particularly with word-level timestamps and confidence scores, is what developer pipelines need to feed into search indexes, analytics, or further processing.
Confidence scores are the fastest route to efficient proofreading. Rather than reading every line at the same pace, scan for segments flagged with low confidence first, since those are statistically where the model struggled, often on names, jargon, or moments where two speakers talked over each other.
A quick QA pass should cover:
- Proper nouns and technical terms the model likely doesn’t recognize.
- Timestamp drift, especially in longer files where small errors compound.
- Speaker labels, particularly in recordings with more than two voices or frequent interruptions.
- Punctuation and sentence breaks, which automated models still get wrong more often than word choice itself.
How Do You Choose the Right Transcription Workflow?
The right workflow depends on four practical questions: how much privacy you need, how much volume you’re processing, whether the task needs to run unattended, and how many languages you’re covering. A single podcast episode transcribed once a month has completely different requirements than a customer support team processing thousands of calls daily.
Industry guidance on this is consistent: pick a transcription platform based on integration needs and feature depth, not on which formats it happens to support, since most modern services already handle OPUS, MP3, and WAV without friction. The real differentiators are diarization quality, language coverage, and how the tool fits into an existing pipeline.
- Local converters make sense for occasional single-file jobs where you already have a preferred desktop tool.
- Online converters work well for quick, low-volume needs with no development required.
- API platforms fit anyone building a repeatable process, handling volume, or needing structured output for downstream systems.
This is where a benchmarking platform like OpenTranscription earns its place for developers and businesses: rather than committing to a single vendor’s model, you compare dozens of transcription models on cost, speed, and accuracy for your specific audio profile, then route jobs accordingly. Add real-time streaming, built-in speaker diarization, and per-second pricing, and the platform handles the automation questions that a one-off online tool simply isn’t built for.
Pro Tip: If you’re transcribing a mix of clean studio audio and low-bitrate voice notes, don’t lock into one model. Benchmarking tools that let you switch models per job type save more proofreading time than any single “best” model ever will.
How Do You Build a Local OPUS Transcription Pipeline?
Developers who need a repeatable, scriptable process typically start with a re-mux step, then hand the file to a local ASR model or an API. The pattern is straightforward:
- Check the container. If a tool rejects
.opus, runffmpeg -i input.opus -c copy output.oggto re-mux without re-encoding, preserving the original audio quality while fixing the extension mismatch. - Skip re-encoding unless you have a specific reason to change bitrate. Re-encoding OPUS audio that’s already compressed tends to compound artifacts rather than fix them.
- Feed the re-muxed file to a local model, or upload it to an API endpoint. Watch for file path issues on batch jobs, chunk long files if the target model has a duration cap, and check rate limits before running large batches through any hosted service.
Pro Tip: When testing a new pipeline, run one short file end-to-end first. It’s the fastest way to catch path errors, encoding mismatches, or rate-limit surprises before you commit an entire batch overnight.
For teams building or debugging audio-handling code more broadly, Vector DSP’s guidance on testing and debugging audio workflows covers integration patterns worth reviewing before you scale a pipeline past a handful of files.
What People Get Wrong About Transcribing Opus Audio
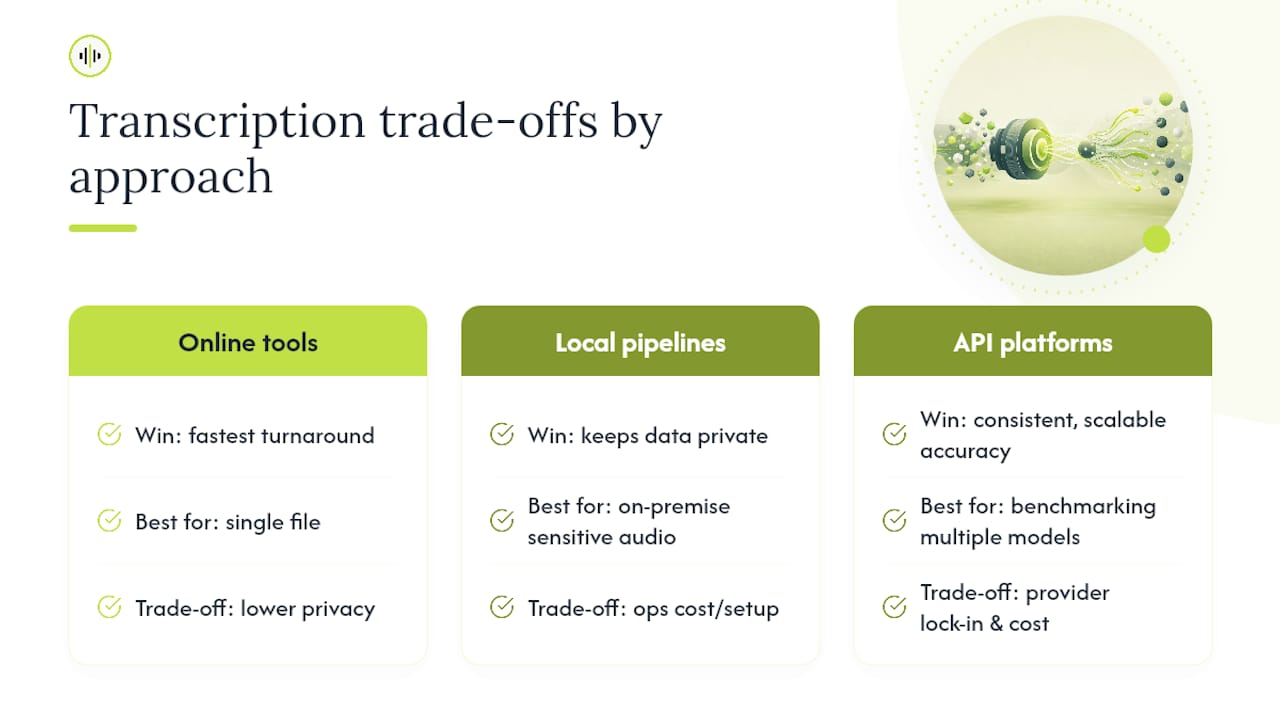
The most common mistake is expecting studio-grade accuracy from a voice note recorded at 24 kbps in a moving car. Compression artifacts are real, and no model fully undoes what a low bitrate already stripped out of the signal. The second mistake is treating container errors as format errors, when a five-second re-mux usually fixes what looks like an incompatibility problem.
The actual trade-off is speed versus privacy versus cost, and there’s no universal answer. Online tools win on speed for a single file. Local pipelines win on privacy when the audio can’t leave your infrastructure. API platforms that benchmark multiple models win when you need consistent, scalable accuracy without betting everything on one provider’s strengths.
— Benjamin
Get Opus Transcription Right the First Time With OpenTranscription
Skipping the trial-and-error of testing five different transcription APIs before finding one that handles OPUS well is the real advantage OpenTranscription offers developers and businesses building production transcription workflows.
Instead of locking into a single vendor’s model and hoping it performs on your specific audio mix, OpenTranscription gives you live access to over 40 speech-to-text models, benchmarked side by side on cost, speed, and accuracy. Real-time streaming and speaker diarization come built in, along with support for 105+ languages and structured transcripts carrying word-level timestamps and confidence scores, exactly the data you need to automate proofreading priorities rather than guess at them. Billing runs per second processed, with no subscription commitment.
If you’re processing OPUS audio at any real volume, whether from voice notes, call recordings, or podcast archives, check the transcription models catalog to compare options against your accuracy and budget requirements before you route a single production job.
Sources
FAQ
Is Opus Audio High Quality?
OPUS delivers strong perceptual quality for voice at modest bitrates, but transcription accuracy specifically depends on staying at or above 64 kbps mono; quality drops noticeably under 24 to 32 kbps.
Is Converting Opus to MP3 Free?
Yes, free tools including ffmpeg convert OPUS to MP3 at no cost, though converting for transcription purposes is often unnecessary since most modern ASR models and platforms like OpenTranscription accept OPUS directly.
Can I Transcribe Audio for Free?
Many online transcription tools offer free tiers with limits on file length or monthly minutes, while pay-as-you-go API platforms like OpenTranscription charge per second processed with no subscription required, which suits occasional or variable-volume use.
Is Opus Better Than Lossless?
No, OPUS is a lossy codec and cannot match true lossless formats like WAV or FLAC for archival fidelity, but it strikes a strong balance of small file size and voice clarity, provided the bitrate stays at 64 kbps or higher.
Why Does My Transcription Tool Reject My Opus File?
The tool likely only accepts specific container extensions rather than rejecting the codec itself; renaming the file to .ogg or re-muxing it with ffmpeg’s -c copy command usually resolves the issue without re-encoding.