
A/B Test Noise Reduction for Transcription on 30–90s Clips, Devs
Don’t denoise by default. Transcribe a short sample both raw and denoised, then keep whichever version produces the lower error rate. The core trade-off is this: noise reduction can strip out both background noise and the acoustic cues a speech recognition model relies on, which sometimes raises word error rate instead of lowering it. Before processing an entire archive, pick one 30 to 90 second noisy clip and run the comparison described below.
TL;DR:
- Denoising can worsen transcription accuracy if it introduces artifacts unfamiliar to the speech recognition model, especially in variable or overlapping noise conditions.
- Light preprocessing works best for steady, low-level background noise and should be tested against raw audio to determine its actual benefit.
- Start with basic audio quality practices such as mono recording at 16 kHz, normalizing levels, and using a high-pass filter before applying any noise reduction.
- Use conservative denoising settings and compare the word error rate of raw versus processed audio to evaluate true improvements.
- Automated, model-aware pipelines that compare multiple transcriptions from raw and denoised samples significantly improve accuracy and efficiency at scale.
Table of Contents
- Why Cleaner Audio Can Sometimes Worsen Transcription Accuracy
- How Do You Decide Whether to Preprocess Audio?
- What Audio Specs Actually Improve Transcription Accuracy?
- Which Tools Work Best for Reducing Transcription Noise?
- How Do You Measure Whether Denoising Actually Helped?
- How Do You Prevent Noise Problems Before You Even Hit Record?
- How Do Model-Aware Pipelines Handle Noisy Transcription?
- An Editorial Take on Model-Aware Noise Reduction
- Test Multiple Models Without Guessing on Noisy Audio
- Where to Go Deeper on Audio Preprocessing
- Sources
- FAQ
Why Cleaner Audio Can Sometimes Worsen Transcription Accuracy
Denoising tools do not surgically remove noise and leave speech untouched. Spectral subtraction, one of the oldest noise reduction techniques, estimates a noise profile and subtracts it from every frame of audio. Done aggressively, it produces “musical noise,” a warbling artifact made of scattered tonal residues that sound nothing like the original environment and nothing like clean speech either. Neural denoisers such as RNNoise and DeepFilterNet avoid musical noise but introduce their own signature: smeared consonants, clipped fricatives, and a slightly synthetic timbre where the model has reconstructed rather than preserved the waveform.
This matters because of how modern automatic speech recognition systems are trained. Whisper and comparable transformer-based models learn from enormous, messy datasets that include plenty of real-world noise: traffic, crosstalk, room echo, HVAC hum. These models have effectively learned what natural noise sounds like sitting behind speech. Denoiser artifacts are a different kind of distortion entirely, one the model has rarely encountered in training, and it can misinterpret that unfamiliar signal as phonetic content. The result is a transcript with new errors that weren’t there in the noisy original.
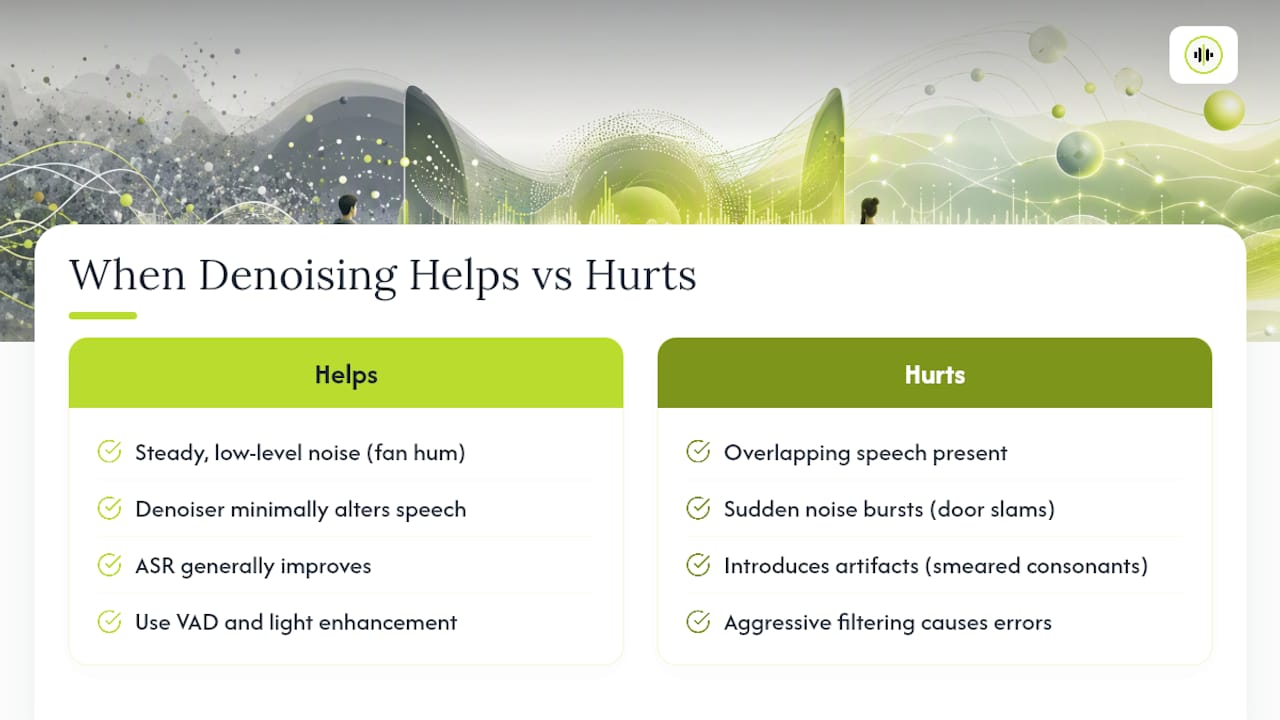
Denoising tends to help when the noise is steady and low-level: a consistent fan hum, a hiss from cheap recording equipment, or a constant air-conditioning drone. It tends to hurt when the recording has overlapping speech, sudden noise bursts like door slams, or when the denoiser is pushed past conservative settings in an attempt to eliminate every trace of background sound. Practitioners working with Whisper consistently report that voice activity detection and light enhancement deliver the safest gains, while heavy-handed filtering is the more common way preprocessing backfires.
How Do You Decide Whether to Preprocess Audio?
Run a quick triage before touching any audio. Ask three questions: Can you understand the speech clearly on headphones despite the noise? Is the noise steady, or does it vary in pitch and volume? Does the recording have multiple people talking over each other? Steady noise with intelligible speech is the best candidate for light preprocessing. Overlapping speech or wildly variable noise is often better left alone, or handled with source separation instead of denoising.
From there, run the actual test:
- Select a representative sample. Pull one file, or a 30 to 90 second clip, that reflects your typical noise conditions rather than your worst-case file.
- Transcribe it raw. Run it through your speech recognition pipeline exactly as recorded, with no processing.
- Apply a conservative denoise. Use moderate settings, not maximum reduction, and export a second version.
- Transcribe the denoised version. Same model, same settings, same pipeline.
- Compare word error rate and listen to both. Lower WER wins, but also scan the transcript for new deletions, which signal that the filter cut speech along with noise.
Keep your original recordings untouched and store denoised copies in a separate folder rather than overwriting anything. If you scale this decision across a larger archive, this A/B habit, not a blanket policy, is what a small, reproducible test on representative segments is built to support.
Pro Tip: Run the A/B test on your noisiest realistic file, not your cleanest one. A denoiser that helps on easy audio can still hurt on your hardest cases, and those are usually the files you care most about getting right.
What Audio Specs Actually Improve Transcription Accuracy?
Most accuracy problems trace back to file preparation, not exotic noise. Getting the basics right before you even consider a denoiser eliminates a surprising share of transcription errors.
- Mono over stereo, except when speakers are split by channel. Downmix general recordings to a single mono track. If you have a dual-channel interview where each speaker has a dedicated mic, keep the channels separate and transcribe them individually for higher per-speaker confidence.
- Sample rate: 16 kHz minimum. Cloud speech-to-text guidance recommends at least 16 kHz, with 44.1 kHz acceptable when file size isn’t a constraint. Lower sample rates cut off frequency information that carries consonant detail, particularly sibilants like “s” and “f” sounds that live above 4 kHz.
- Bit depth: 16-bit. This keeps quantization noise low without inflating file size the way 24-bit or 32-bit float recordings do for a task that doesn’t need that dynamic range.
- Normalize to sane levels, not maximum loudness. Target peaks around negative 3 dB and aim for consistent RMS levels across a file. Avoid clipping entirely; clipped peaks introduce harsh digital distortion that no denoiser can undo.
- High-pass filter around 80 to 100 Hz. This removes low-frequency rumble, handling noise, and HVAC drone that sits below the speech range without touching vocal content.
- Trim silence and non-speech segments with voice activity detection. VAD identifies where speech actually occurs and can strip dead air, which shortens processing time and reduces the chance that a model transcribes silence as phantom words.
The single most important rule across all of this: apply one filter at a time and check the result before stacking another. Google’s own optimization guidance frames mono conversion, 16-bit depth, and standard sample rates as the baseline that balances file size against speech frequency response, not as one step in a longer chain of aggressive processing. Chaining a high-pass filter, a compressor, a noise gate, and a neural denoiser in sequence multiplies the risk of artifacts, and by the time something goes wrong, it’s difficult to tell which step caused it.
Which Tools Work Best for Reducing Transcription Noise?
Every tool here has a role, but the common thread is restraint. Conservative settings consistently outperform maximum-strength settings when the output feeds an ASR model rather than a human ear.
Audacity remains the fastest way to hand-tune a noise reduction pass. Select a few seconds of pure noise (a “noise print”), open Effect > Noise Reduction, generate the noise profile from that selection, then apply the effect to the full track. Practical guidance on this workflow recommends 8 to 12 dB of reduction with moderate sensitivity and light smoothing. Pushing much beyond that range is where musical noise and consonant smearing start showing up.
ffmpeg is the better choice once you need to batch-process dozens or hundreds of files. A one-line command like ffmpeg -i input.wav -af "highpass=f=90,loudnorm" output.wav applies a high-pass filter and loudness normalization in a single pass, and it’s trivial to wrap in a shell script for an entire folder.
Neural denoisers like RNNoise and DeepFilterNet outperform traditional spectral subtraction for steady background noise: HVAC hum, traffic, fan noise. DeepFilterNet’s own documentation notes it’s effective at isolating voice in many real-world conditions, but the same source cautions that outputs should be tested before deployment, since the reconstruction can confuse an ASR model even when it sounds cleaner to a human.
Demucs, originally built for music source separation, has found a second life pulling apart overlapping speech. It’s most useful when two people talk over each other on a single microphone; it’s far less useful, and often counterproductive, on already-clean single-speaker audio.
- Convert and normalize with ffmpeg first (mono, 16 kHz, high-pass, loudnorm).
- Denoise conservatively only if your triage flagged steady background noise.
- Run VAD to trim silence before transcription.
- Feed both the raw and processed versions into your transcription pipeline and compare.
Community projects like Audify demonstrate combined DeepFilterNet-plus-Whisper pipelines, which are worth studying as a template even though results still need validation against your own audio.
Pro Tip: Script your preprocessing chain once, then run it identically across every file in a batch. Manual, file-by-file tweaking in Audacity introduces inconsistency that makes your A/B comparisons unreliable across a larger dataset.
How Do You Measure Whether Denoising Actually Helped?
Word error rate is the standard yardstick: the sum of substitutions, deletions, and insertions divided by the total number of words in a reference transcript. Compute it separately for your raw and denoised versions on the same test set, and break the errors down by type rather than looking at the aggregate number alone.
That breakdown matters more than the headline figure. A rise in deletions specifically signals that a filter is cutting speech along with noise, even when the overall WER looks like an improvement. A transcript that drops three words but fixes five misheard ones might show a lower WER while quietly removing content a human reviewer would flag as missing.
- Prepare a test set of 5 to 10 representative files with human-verified reference transcripts.
- Transcribe each variant (raw, conservatively denoised, aggressively denoised if you’re curious) through the identical pipeline.
- Compute WER for each variant and log the substitution, deletion, and insertion counts separately.
- Listen specifically to segments where the transcripts disagree, not the whole file.
- Track the model’s confidence scores as a secondary signal; a denoised version with lower confidence despite similar WER is a warning sign, not a win.
For small test sets, a single comparison can mislead you. Bootstrap resampling, repeatedly sampling subsets of your test files and recalculating WER, gives a distribution instead of one number, which helps you see whether a small WER improvement is a real signal or noise from having too few files. With five files, one unusually hard clip can swing your entire result.
How Do You Prevent Noise Problems Before You Even Hit Record?
The cheapest noise reduction happens before recording starts, not after. A closer microphone and a quieter room solve problems no software can fully undo, because once noise and speech are mixed into the same waveform, separating them perfectly is not physically possible.
- Choose the right microphone for the setting. A lapel or lavalier mic works well for mobile interviews and keeps the capsule close to the mouth regardless of head movement. A cardioid condenser suits controlled studio or home-office recording, rejecting sound from the sides and rear. Headset mics are the most reliable option for calls and remote interviews since distance never varies.
- Keep the microphone close. Signal-to-noise ratio degrades fast with distance; doubling the distance between mouth and mic roughly halves the direct signal relative to ambient noise. Six to twelve inches is a solid working range for most cardioid mics.
- Treat the room, even minimally. Close windows and doors, turn off fans and HVAC where possible, and record in a space with soft furnishings, a rug, curtains, upholstered furniture, rather than a bare room with hard, reflective walls that cause echo.
- Protect against wind outdoors. A foam windscreen or furry “deadcat” cover cuts low-frequency rumble that a high-pass filter alone can’t fully remove without also dulling speech.
- Record a few seconds of ambient noise before speaking. This noise print gives you a reference sample if you do end up needing Audacity’s noise reduction tool, and it costs nothing to capture. For multilingual or multi-speaker production setups, structured preprocessing workflows built around consistent capture conditions save far more cleanup time downstream than any single software fix.
How Do Model-Aware Pipelines Handle Noisy Transcription?
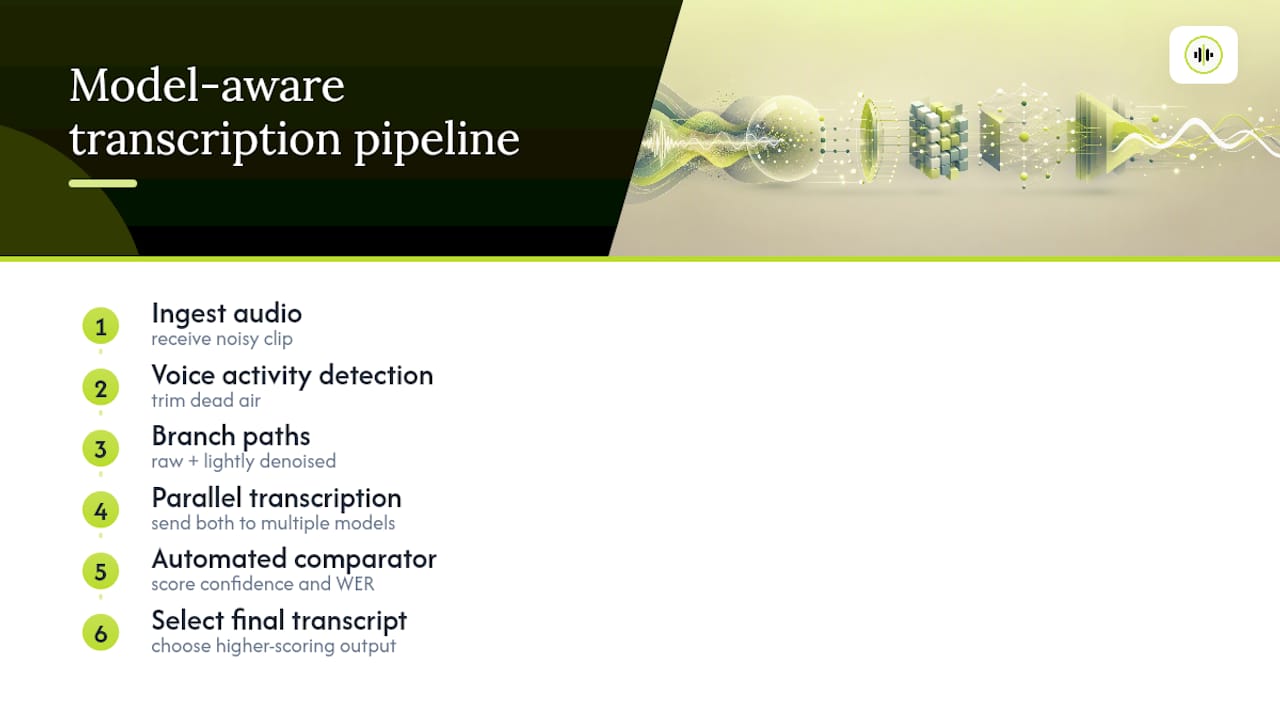
A production pipeline built for noisy audio looks different from a single “denoise and hope” step. The pattern that scales: ingest the audio, run voice activity detection to trim dead air, branch into two paths, one raw and one lightly denoised, transcribe both in parallel, then run an automated comparator that scores each output on model confidence and estimated word error rate before selecting the final transcript.
OpenTranscription’s API is built around exactly this kind of parallel testing. Because the platform benchmarks and routes across more than 30 transcription models, you can send the same noisy file to several engines at once, including newer entrants like Gemini 3.5 Transcribe, which has shown improved robustness in noisy conditions relative to earlier generations, rather than betting on a single model’s behavior with degraded audio. Every transcript returns with word-level confidence scores, which gives you a concrete signal for the automated comparator step instead of relying on manual listening for every file.
For teams processing volume, that architecture replaces hours of manual A/B listening with a repeatable, automated decision. The gain isn’t a magic accuracy boost. It’s speed: reaching the same test-first conclusion this article recommends, at scale, without a human reviewing every file pair by hand.
An Editorial Take on Model-Aware Noise Reduction
Most advice on this topic still treats denoising as a hygiene step, something you do reflexively before transcription the same way you’d trim silence or check your levels. That framing is outdated for anything running on a modern transformer-based ASR model. These systems were trained on oceans of imperfect, noisy real-world audio, and they’re often better at handling that mess than at handling the synthetic artifacts a denoiser leaves behind.
The practical shift worth making is treating preprocessing as a hypothesis to test, not a step to apply. Transcribe raw first. Only reach for Audacity, ffmpeg, or a neural denoiser when the raw transcript’s error pattern tells you noise is genuinely the bottleneck, not because a checklist said to clean the audio before sending it anywhere.
If there’s one thing worth prioritizing over every technique in this article, it’s building the habit of comparing raw against processed output on every new source of audio, not just once. Noise conditions change between recordings; a workflow that worked for one podcast’s studio setup can quietly fail on a field interview recorded near traffic.
— Benjamin
Test Multiple Models Without Guessing on Noisy Audio
Every workflow described above hinges on being able to compare transcripts side by side, quickly, without manually running the same file through five different systems and reconciling the output by hand. That’s the specific gap OpenTranscription closes: one API that routes the same audio across more than 30 speech-to-text models, returns word-level confidence scores on every transcript, and bills per second of audio processed instead of locking you into a subscription you don’t need for occasional or bursty transcription work.
For the A/B test described earlier in this article, that means sending your raw and denoised samples through the same call and comparing confidence scores and output directly, rather than juggling separate accounts for each engine you want to test. If you’re deciding which model handles your specific noise conditions best, the transcription models catalog breaks down what’s available, and the realtime rankings page shows how models stack up on live streaming performance. Run your noisiest sample file through the platform today and see which model actually produces the lowest error rate on your audio, not on a benchmark dataset.
Where to Go Deeper on Audio Preprocessing
For hands-on technical work, Google’s Cloud Speech-to-Text optimization guidance covers file format specifics in more depth than any single article can. The OpenAI Whisper discussion thread on preprocessing is worth reading in full for real practitioner disagreements. DeepFilterNet’s repository documents the model itself, and Audacity’s and ffmpeg’s own documentation remain the fastest references for exact filter syntax.
Sources
- Optimize audio files for Cloud Speech-to-Text | Google Cloud Documentation
- Audio Preprocessing That Improves Accuracy · Multigrid
- do whisper need preprocessing, enhancing, or denoising audio before transcribing? — OpenAI Whisper discussions
FAQ
How Can I Remove Hiss From Audio?
Steady hiss responds well to Audacity’s noise reduction tool: select a few seconds of pure hiss to build a noise profile, then apply 8 to 12 dB of reduction with moderate sensitivity. Heavier settings risk introducing musical noise artifacts that can confuse transcription models.
What Are Effective Noise Reduction Techniques for Transcription?
The most reliable techniques are voice activity detection to trim silence, conservative spectral or neural denoising for steady background noise, and high-pass filtering around 80 to 100 Hz to remove low-frequency rumble. The safest approach is testing each technique’s transcript against the raw version rather than applying it by default.
How Do You Isolate Speech From Background Noise?
For steady noise, neural denoisers like DeepFilterNet or RNNoise isolate speech effectively in many conditions, though outputs should be checked for artifacts before trusting them. For overlapping speech from multiple people on one microphone, source separation tools like Demucs handle the problem better than standard denoisers.
How Do I Stop a Mic From Picking Up Background Noise?
Move the microphone closer to the speaker’s mouth, since signal-to-noise ratio drops fast with distance, and choose a cardioid or lapel mic that rejects sound from the sides and rear. Closing windows, turning off fans, and recording in a room with soft furnishings reduces ambient noise before it ever reaches the recording.
Does Denoising Always Improve Transcription Accuracy?
No. Denoising can raise word error rate by introducing artifacts the speech recognition model wasn’t trained to handle, particularly with aggressive settings. Testing a sample both raw and denoised, then comparing error rates, is the only reliable way to know which version performs better for a given file.