
Low Latency Transcription: Benchmarks, Tactics, and Targets
For voice agents and conversational interfaces, target total end-to-end latency under 300 milliseconds; for live captions, 150 to 300 milliseconds keeps text visually synchronized with speech; for meeting notes or asynchronous review, sub-second delivery is acceptable. Reaching those numbers is an architecture decision, not a model decision alone. Start with these three moves.
- Shrink client audio buffers smaller than typical defaults most SDKs ship with.
- Turn on partial transcript commits so the interface shows tentative words while the model keeps refining them.
- Select a low-latency streaming model, or move inference on-device, based on how much your network conditions vary.
None of these numbers mean anything until you test them against your own audio, with your own microphones, background noise, and accents. Vendor benchmarks are a starting point, not a guarantee.
Key Takeaways
Low latency transcription depends on tuning buffer size, chunking, and model delay settings together, then validating the result against representative audio rather than vendor benchmarks alone.
| Point | Details |
|---|---|
| Set a clear latency target first | Pick under 300 ms for voice agents, 150 to 300 ms for captions, before choosing any tools. |
| Fix transport before blaming the model | Persistent WebSocket connections and regional endpoints often cut more delay than a model swap. |
| Emit partials, commit finals later | This single change delivers the biggest perceived latency improvement for most interactive apps. |
| Test WER per latency bucket | Build a matrix of latency target × model delay setting × WER using real, noisy audio. |
| Benchmark across models before integrating | OpenTranscription’s realtime rankings let you compare latency and accuracy across 40+ models on one API before committing to a build. |
Table of Contents
- What Are the Core Metrics for Low Latency Transcription?
- What Causes Latency in a Transcription Pipeline?
- How Do You Reduce Latency Without Losing Accuracy?
- How Should You Test the Accuracy and Latency Tradeoff?
- Should You Run Transcription On-Device, in the Cloud, or Hybrid?
- What Should Your Implementation Checklist Look Like?
- How Do You Maintain Latency With Noisy or Multi-Speaker Audio?
- How Should Real-Time Transcripts Feed Downstream Applications?
- How Do Audio Encoding and Transport Protocols Affect Latency?
- How Do You Scale Low Latency Transcription Across Many Concurrent Streams?
- Does Latency Optimization Change by Language or Accent?
- Why Most Teams Optimize the Wrong Latency Number First
- How to Benchmark Latency Across Models in Minutes
- Sources
- FAQ
What Are the Core Metrics for Low Latency Transcription?
Four numbers matter, and teams that only track one of them usually optimize the wrong stage of the pipeline.
- Word-emission latency: the time between a word being spoken and its text appearing on screen, even as a partial hypothesis.
- Transcription latency: the model’s own processing time, isolated from network transit, calculated as
server_receive_timeminusmodel_emit_time. - End-of-turn (EOT) latency: the delay between a speaker finishing and the system recognizing the turn has ended, which determines how fast a voice agent can respond.
- Total end-to-end latency:
client_render_timeminuscapture_time, the number your users actually feel.
To compute these, timestamp five points: audio capture, client send, server receive, model emit, and client render. Subtracting consecutive pairs gives you each component. Deepgram’s measurement guidance breaks total transcript latency into network transit time, transcription latency, and client processing, and recommends client buffer sizes of 20 to 100 milliseconds to keep the first stage from dominating the budget. Vendors like ElevenLabs advertise streaming latency near 150 milliseconds for their realtime model, which is a useful reference point for what a well-tuned pipeline can achieve, though your mileage depends heavily on network path and audio quality.
What Causes Latency in a Transcription Pipeline?
Delay accumulates at five distinct stages, and each one responds to a different fix.
- Client capture and encoding: large frame sizes, low sample rates chosen for bandwidth savings, and codec compression all add milliseconds before audio even leaves the device.
- Network setup and transit: DNS resolution, TLS negotiation, and WebSocket handshake costs are one-time penalties that a persistent connection avoids on every subsequent utterance.
- Server buffering and chunking policy: many backends wait to accumulate a full chunk before processing, trading latency for slightly more context per inference call.
- Model inference time: batching requests improves throughput for batch transcription jobs but directly hurts interactive latency, since a request waits for the batch to fill.
- VAD, endpointing, and post-processing: voice activity detection thresholds and punctuation or formatting passes run after the acoustic model, adding sequential delay on top of raw inference.
Most teams inspect the model first because it is the most visible component. In practice, buffering policy and connection setup often account for more of the delay budget than the model itself.
How Do You Reduce Latency Without Losing Accuracy?
Work through these tactics roughly in order. Each one is independently testable, so you can measure the latency delta before moving to the next.
- Set client audio frames to 20 to 100 milliseconds. Larger frames reduce per-packet overhead but delay everything downstream; smaller frames raise packet count without buying you meaningful accuracy.
- Lower VAD sensitivity carefully. An aggressive voice activity detector cuts off speech early, but a lax one adds unnecessary silence padding before the system commits to processing.
- Reuse persistent WebSocket connections. Reconnecting per utterance re-pays the DNS, TLS, and handshake cost every time, which can add hundreds of milliseconds you never needed to spend.
- Route to regional endpoints. Co-locating your client’s nearest server region with your model inference cuts transit time directly, since data does not need to cross continents.
- Emit partial hypotheses early, commit final text later. This is the single highest-leverage change for perceived latency; users see responsive text immediately, and the system quietly corrects it before finalizing.
- Tune the model’s delay setting. OpenAI’s realtime transcription guidance exposes delay levels from minimal to xhigh, explicitly trading responsiveness for transcript quality, and recommends starting at minimal or low for latency-sensitive use cases.
- Avoid server-side batching for interactive flows. Reserve batching for offline or asynchronous jobs where throughput matters more than any single response time.
- Render partials with a visual tentative flag. Show unconfirmed text in a lighter color or with a subtle marker so users understand it may still change.
Pro Tip: Measure each tactic’s impact separately before stacking them. Combining buffer size changes with model delay changes in the same test run makes it impossible to tell which lever actually moved the needle.
How Should You Test the Accuracy and Latency Tradeoff?
Fix your latency buckets first, then measure word error rate (WER) inside each one. A common test matrix runs three latency targets (under 300 milliseconds, 300 to 600 milliseconds, over 600 milliseconds) against two or three model delay settings, producing a grid of WER scores you can actually compare.
- Use representative audio: real microphones, not studio recordings, plus background noise, varied accents, and your actual domain vocabulary.
- Run the same audio through every cell in the matrix so differences reflect configuration, not source variation.
- Read the results as a tradeoff curve, not a single winner; the “best” configuration depends on whether your product tolerates occasional errors more than it tolerates delay.
- Validate in staging with sampled production traffic before committing to a configuration company-wide.
Experts consistently recommend picking your target latency and accuracy threshold before testing, then stress-testing that specific configuration against real-world conditions rather than synthetic samples. Skipping this step is the most common reason teams discover accuracy problems only after shipping.
Should You Run Transcription On-Device, in the Cloud, or Hybrid?
The right deployment model depends on which variable you can least afford to lose control over: latency predictability, raw accuracy, or network reliability.
- On-device: latency is deterministic because there’s no network hop, and it works offline. Picovoice’s Cheetah Streaming reports word-emission latency in one benchmark of around 590 milliseconds, achieved specifically by removing network variability from the equation. The tradeoff is constrained compute, which usually means a smaller model and more tuning work to hit your accuracy bar.
- Cloud: gives you access to larger, more accurate models and elastic scale, but network conditions introduce variability you can’t fully control. Regional endpoints and co-locating client and server infrastructure reduce transit time meaningfully.
- Hybrid: run VAD and partial results on-device for instant feedback, then send audio to the cloud for a more accurate final transcript. This pattern suits flaky networks or privacy-sensitive flows where you want a local fallback if connectivity drops.
What Should Your Implementation Checklist Look Like?
Before shipping, confirm your logging, fallback, and scaling behavior are all instrumented, not just your happy-path latency numbers.
- Log five timestamps per request:
capture_time,send_time,server_receive,model_emit, andclient_render. Correlate them with a unique request ID generated at capture time. - Analyze percentiles, not averages. A practical instrumentation pattern from VideoSDK’s realtime transcription documentation stores p50, p90, and p99 for each component, since tail latency is what users actually notice and complain about.
- Build fallback behaviors: a smaller, faster model to downgrade to under load; a local-partials-only mode when the network drops; a manual quality-over-latency toggle for power users.
- Harden connection handling: connection pooling, exponential backoff on reconnect, and periodic health checks prevent a single dropped socket from cascading into a full session failure.
- Test for concurrency effects before you need to. Backpressure and queue-size limits behave differently at 10 concurrent streams than at 1,000, and that difference only shows up under load testing.
Pro Tip: Store your p99 latency trend over time, not just a snapshot. A model or region change that looks fine on average can quietly push your worst-case users into a noticeably worse experience.
How Do You Maintain Latency With Noisy or Multi-Speaker Audio?
Background noise and overlapping speakers put pressure on the exact same components that already dominate your latency budget, which means fixes here can’t come at the cost of the tuning you already did upstream.
Noise primarily degrades VAD accuracy. A voice activity detector tuned for quiet rooms either triggers on background chatter, sending unnecessary audio for processing, or fails to detect speech promptly, adding delay before transcription even starts. Retuning VAD thresholds against your actual noise profile, not a generic default, is usually the fastest fix and doesn’t touch your model or transport layer at all.
Multi-speaker environments add a second problem: speaker diarization. Assigning words to the correct speaker is computationally more expensive than single-speaker transcription, and running diarization as a blocking step before emitting any text will visibly slow perceived latency. The better pattern separates the two concerns: emit transcript text with low latency first, then attach speaker labels as a secondary, slightly delayed enrichment layer that updates the UI once available. This keeps the text your users read responsive while diarization catches up a beat behind it.
For genuinely difficult audio, such as overlapping speech or heavy crosstalk, accept that WER will rise regardless of latency tuning, and design your interface to communicate uncertainty (lower confidence scores, visual flags on ambiguous segments) rather than silently presenting degraded transcripts as fully reliable.
How Should Real-Time Transcripts Feed Downstream Applications?
Transcription rarely exists as an end product. It usually feeds a voice agent’s response logic, a live captioning overlay, a search index, or an analytics pipeline, and each of those downstream consumers has different tolerance for partial or revised text.
For voice agents, end-of-turn detection matters more than raw transcription speed. An integrated EOT model reduces response latency compared with a separate VAD pipeline because it short-circuits the extra step of waiting for a standalone silence detector to confirm the turn has ended before the agent’s response logic even starts, according to Deepgram’s developer documentation. If your agent waits for a fully finalized transcript before generating a reply, you’re adding the model’s full commit delay on top of its own response time.
For live captioning, the UI feedback loop is the product. Captions that appear, then get corrected a half-second later, need a visual convention (fading text, a subtle strikethrough, color shift) so viewers don’t distrust every word they see. Sentop’s overview of real-time translation in video meetings walks through how conferencing platforms handle this same problem when layering live captions and translation on top of a video stream, and the same pattern for signaling tentative versus confirmed text applies directly to transcription-only interfaces.
For analytics or search indexing, the calculus flips: you generally want the finalized, corrected transcript rather than the fastest partial, since indexing a wrong word is worse than indexing it a second late.
How Do Audio Encoding and Transport Protocols Affect Latency?
The codec and protocol you choose set a hard floor on latency before your model ever sees a single frame.
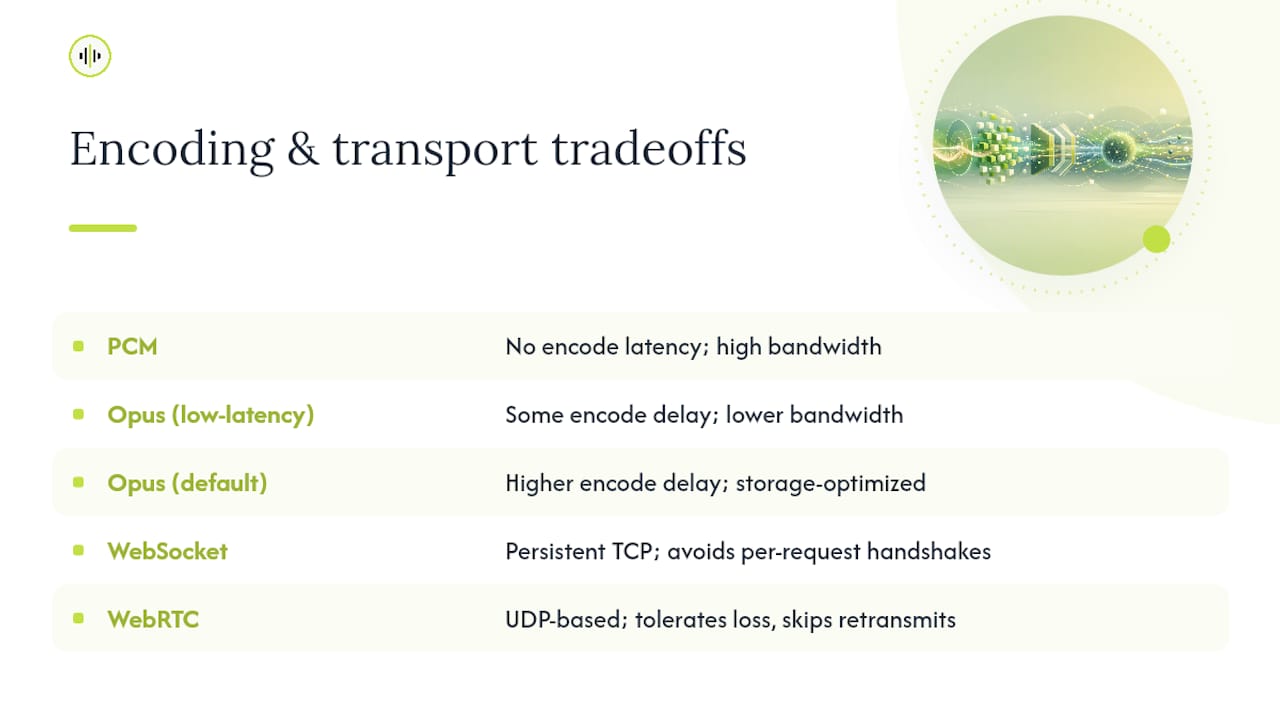
Codec choice matters more than most teams assume. Compressed formats like Opus reduce bandwidth but add encoding and decoding time on both ends of the connection; raw PCM audio skips that step entirely at the cost of higher bandwidth use. For latency-sensitive streaming, PCM or a low-latency Opus configuration typically outperforms formats designed for storage efficiency rather than real-time transmission.
Transport protocol matters just as much. WebSocket connections, kept persistent across an entire session, avoid repaying the TCP handshake and TLS negotiation cost on every utterance, which is exactly the overhead that a fresh HTTP request per audio chunk would force you to eat repeatedly. WebRTC, built specifically for real-time media, adds further latency advantages through its use of UDP-based transport, which tolerates some packet loss in exchange for skipping TCP’s retransmission delays, a tradeoff that suits live audio far better than reliable-but-slower delivery.
Sample rate is a smaller but real lever: 16kHz is the practical floor for most speech recognition models, and going lower saves bandwidth while measurably hurting both latency (through added resampling steps) and accuracy. Going higher than what your model was trained on rarely improves results and simply adds transmission overhead.
How Do You Scale Low Latency Transcription Across Many Concurrent Streams?
A pipeline tuned for one stream at 100 milliseconds latency can silently degrade to 400 milliseconds once you’re running 500 concurrent sessions, and the failure mode is rarely obvious until it’s already affecting users.
The core tension is between per-stream latency and aggregate throughput. Server-side batching, which groups multiple requests into a single inference call, is excellent for throughput but actively hurts interactive latency, since each request waits for the batch to fill or for a timeout to trigger. At scale, teams often run two separate inference paths: a low-latency path with no batching for interactive streams, and a batched path for asynchronous or bulk transcription jobs, rather than forcing every workload through one configuration.
Backpressure handling becomes critical once concurrency climbs. Without queue-size limits, a burst of simultaneous connections can overwhelm inference capacity, and the resulting delay hits every active session rather than just the new arrivals. Setting explicit queue caps, and returning a clear degraded-service signal rather than silently queuing indefinitely, keeps a traffic spike from becoming a latency incident across your entire user base.
Load testing needs to specifically target concurrency, not just total request volume. A system handling 1,000 sequential requests smoothly can behave very differently under 1,000 simultaneous connections, because connection pooling, thread limits, and per-instance memory constraints only show their limits under real concurrent pressure.
Does Latency Optimization Change by Language or Accent?
Yes, and this is one of the more overlooked variables in latency tuning. Models trained predominantly on one language or a narrow set of accents tend to need more processing time, or produce lower confidence scores, when handling speech outside that training distribution, which indirectly affects perceived latency through more frequent re-processing or correction passes.
Tonal languages and languages with different phoneme timing than English can also interact differently with VAD and endpoint detection tuned around English speech patterns, sometimes triggering premature or delayed end-of-turn signals. If you’re deploying across multiple languages, retesting your VAD thresholds and delay settings per language, rather than assuming one global configuration works everywhere, is worth the extra benchmarking cycle.
For accented speech within a single language, the practical fix is rarely a latency setting at all. It’s model selection: some models handle a wider range of accents at comparable speed, while others show a real accuracy drop that no amount of latency tuning will fix. This is exactly the kind of variable that benchmarking across model options, rather than assuming your default model handles every accent equally well, will surface quickly.
Why Most Teams Optimize the Wrong Latency Number First
The instinct when a transcription pipeline feels slow is to swap the model. That’s usually the least effective fix, and it’s the one most teams reach for first because it’s the most visible knob available to them.
In practice, buffer size and connection handling account for a surprising share of perceived latency, and they’re free to fix. A team running a genuinely fast model behind a 400 millisecond client buffer and a fresh WebSocket handshake per utterance will feel slower than a team running a mediocre model behind a 50 millisecond buffer and a persistent connection. The model gets blamed for what the transport layer actually caused.
The other blind spot is treating latency and accuracy as a single number to optimize rather than a curve to choose a point on. There is no universal “best” configuration. A voice agent handling appointment scheduling can tolerate a slightly higher error rate in exchange for sub-300 millisecond responses; a legal transcription tool cannot tolerate that same error rate at any speed. Teams that skip building the latency bucket versus WER test matrix end up shipping whatever default configuration felt fastest in a demo, then discover the real accuracy cost weeks later in production.
The uncomfortable truth is that vendor-published latency numbers, including the ones cited throughout this piece, describe best-case conditions. Representative testing against your own noisy, accented, multi-speaker audio is the only number that matters, and it’s also the step most teams are tempted to skip because it takes longer than reading a spec sheet.
— Benjamin
How to Benchmark Latency Across Models in Minutes
Choosing a latency and accuracy target on paper is the easy part. Confirming which model actually hits that target on your audio, without weeks of custom integration work for each candidate, is where most teams stall out. OpenTranscription exists specifically to close that gap: instead of wiring up separate SDKs for every provider you want to test, one API gives you access to more than 40 transcription models with unified structured output, word-level timestamps, and confidence scores.
Running a real comparison takes less than half an hour. Stream a representative sample of your actual audio, capture the same five timestamps discussed earlier in this article, and compare word-emission latency and WER side by side using the realtime model rankings. If a particular model looks promising, check its full profile in the models catalog before committing engineering time to a deeper integration. Billing runs per second of audio processed with no subscription commitment, so a benchmarking pass costs you exactly what you use and nothing more. Start your comparison on the OpenTranscription platform and see which model actually meets your latency bucket on your own audio, not a vendor’s demo recording.
Sources
FAQ
What Counts as a Good Words-per-Minute Rate for Transcriptionists?
Human transcriptionists typically produce accurate output at around 40 words per minute, well below normal conversational speech rates. This is exactly the gap automated low latency transcription closes for real-time use cases where waiting for a human isn’t an option.
What Does Low Latency Communication Actually Mean?
Low latency communication means the delay between an action and its visible or audible response stays small enough that the interaction feels instantaneous, generally under 300 milliseconds for conversational systems. In transcription specifically, that delay is measured from audio capture to rendered text on screen.
What’s the Best Way to Get Voice Chat Without Noticeable Delay?
Voice chat without noticeable delay depends on persistent low-latency connections, small audio buffers of 20 to 100 milliseconds, and endpoint detection tuned to your environment rather than left at default settings. The transport layer, not just the model, usually determines whether delay is noticeable.
Can You Realistically Earn $1,000 a Month Doing Manual Transcription?
Freelance transcriptionists can reach roughly $1,000 a month at typical per-audio-minute rates, but it usually requires steady client volume and consistent turnaround, which is one reason many businesses shift high-volume or time-sensitive transcription work to automated pipelines instead.
How Do I Choose Between Different Transcription Models for Low Latency?
Compare candidate models on the same representative audio using a shared latency bucket and WER matrix rather than trusting published specs alone. Platforms like OpenTranscription let you run that comparison across more than 40 models without building a separate integration for each one.