
For streaming-first voice agents, Deepgram is the stronger default; for integrated audio intelligence and stable interim transcripts, AssemblyAI is the stronger choice. If you need to validate that decision against your own audio before committing, OpenTranscription benchmarks both across 40+ models in a single harness.
If you read only one sentence: Deepgram wins on throughput and turn-taking latency; AssemblyAI wins on transcript stability and analytics depth; use OpenTranscription to measure which trade-off actually matters for your workload.
| Platform | Best for | Accuracy | Latency | Key differentiator |
|---|---|---|---|---|
| OpenTranscription | Benchmarking and model routing | 40+ models ranked | Real-time ranker | Unified model catalog, per-second billing |
| Deepgram | Voice agents, streaming | High, speed-tuned | Sub-300ms turn detection | Flux evented EndOfTurn primitives |
| AssemblyAI | Audio analytics, meeting assistants | High, accuracy-tuned | ~300ms immutable partials | Universal-Streaming immutability |
| Gladia | Enterprise batch workflows | Solid | Batch-oriented | Enterprise pipeline integrations |
| OpenAI Whisper | Self-hosted batch transcription | Strong (offline) | Not streaming-native | Open-source, full model control |
Table of Contents
- How do Deepgram and AssemblyAI compare side by side?
- What do benchmarks actually tell you about production performance?
- Which streaming features matter most for production voice and transcript apps?
- Does fine-tuning or custom vocabulary change which API you should pick?
- What does pricing actually look like for real workloads?
- What security and compliance posture should you require from any STT provider?
- How does developer experience affect time-to-value?
- How should you choose between these APIs for your specific project?
- What is the right API for each production use case?
- Key Takeaways
- The case for measuring before you commit
- OpenTranscription cuts the time between evaluation and production
- Useful sources
How do Deepgram and AssemblyAI compare side by side?
The table below covers the decision-critical dimensions developers need before reading deeper. Independent analysis frames the core split plainly: “Deepgram is obsessed with Speed and Throughput. AssemblyAI is obsessed with Understanding and Accuracy.” That framing holds across nearly every dimension below.
| Dimension | OpenTranscription | Deepgram | AssemblyAI | Gladia | OpenAI Whisper |
|---|---|---|---|---|---|
| Accuracy (WER) | Routes to best model | Speed-tuned, competitive | Accuracy-tuned, competitive | Solid for enterprise batch | Strong offline |
| Streaming latency | Real-time ranker | Sub-300ms end-of-turn (Flux) | ~300ms immutable partials | Batch-oriented | Not streaming-native |
| Best-for use case | Model selection and routing | Voice agents, live bots | Meeting assistants, analytics | Enterprise batch transcription | Batch, self-hosted |
| Diarization | Model-dependent | Yes | Yes | Yes | Limited (requires add-ons) |
| Turn detection | Model-dependent | Evented (StartOfTurn/EndOfTurn) | Acoustic + semantic + silence fusion | Limited | None native |
| Custom vocab / fine-tuning | Depends on routed model | Keyword boosting, fine-tuning | Custom vocab, LeMUR prompting | Custom vocab | Full fine-tuning (self-managed) |
| Language coverage | 105+ languages | 30+ languages | 99+ languages | Multilingual | 99+ languages |
| Pricing model | Per-second, pay-as-you-go | Per-second | Per-second | Per-minute/enterprise | Hosting cost only |
| Deployment | Cloud API | Cloud, VPC, on-prem | Cloud, enterprise private | Cloud | Self-hosted |
| Developer experience | Unified SDK, model switching | Strong SDKs, active docs | Strong SDKs, LeMUR integration | REST-focused | Community-maintained |
Deepgram’s cloud, VPC, and on-prem options give it a structural advantage for regulated or latency-sensitive deployments. AssemblyAI is primarily cloud-hosted, with private deployment available under enterprise arrangements. OpenAI Whisper sits in a different category entirely: it is a self-hosted model, not a managed API, which means you own the infrastructure, the VAD pipeline, and the endpointing logic.
Pro Tip: Vendor-published WER figures are measured on curated benchmark sets, not your audio. Before weighting any accuracy claim, run the same 10-sample set through each candidate API in the same network region and measure end-to-end latency, word error rate, and formatting quality yourself.
What do benchmarks actually tell you about production performance?
The most consequential insight for voice-agent teams is that published WER leaderboards measure the wrong thing: “A voice agent is not transcribing a file. It’s holding a conversation in real time, and what makes that conversation feel human is latency and turn-taking — neither of which the leaderboard measures at all.”
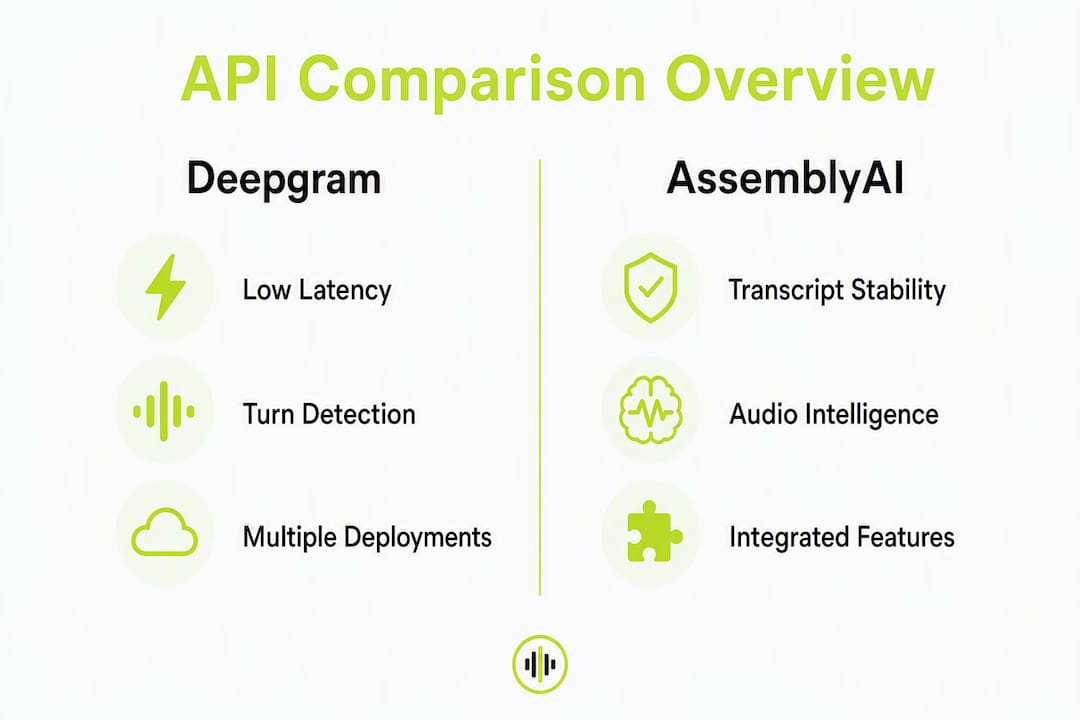
For batch pipelines, WER and real-time factor (RTFx) are the right primary metrics. For live voice agents, end-of-turn latency and interim transcript stability matter far more than a two-point WER difference.
| Metric | Batch pipelines | Live voice agents |
|---|---|---|
| WER | Primary | Secondary |
| RTFx | Primary | Relevant |
| End-of-turn latency | Not applicable | Primary |
| Interim stability | Low importance | Critical |
| Throughput (concurrent streams) | Moderate | High |
Deepgram’s Flux model targets a median EndOfTurn latency notably below 1 second, aiming to reduce response latency significantly compared to stitched STT-plus-VAD pipelines. AssemblyAI’s Universal-Streaming delivers partials in roughly 300ms, with the architectural guarantee that those partials are immutable once emitted.
Testing methodology you can reproduce
Consistent benchmark design requires identical audio routed through each provider in the same network region, with unified evaluation metrics: WER, end-to-end latency, RTFx, formatting quality, and cost per audio hour. A representative test set should include short utterances (under 3 seconds), overlapping speakers, low-SNR telephony recordings, domain-specific named entities, and long-form recordings to catch timestamp and formatting regressions.
Pro Tip: Build your benchmark set around the failure modes that will hurt you in production: silence segments (to catch hallucination), rapid speaker switches (to stress diarization), and entity-heavy domain vocabulary (to expose vocabulary gaps). A generic read-speech corpus will not reveal these.
Which streaming features matter most for production voice and transcript apps?
Turn detection is not a UX nicety. It prevents race conditions between intermediate transcripts and downstream LLM reasoning, and the two leading APIs solve it with architecturally distinct approaches.
Deepgram Flux emits explicit StartOfTurn and EndOfTurn events. The model fuses acoustic and prosodic signals to decide when a speaker has finished, then fires a discrete event the orchestration layer can act on immediately. This evented model is well-suited to agent frameworks that need a clean trigger to dispatch an LLM call. The Flux turn-detection architecture represents a meaningful departure from the older VAD-plus-silence-timeout approach that most stitched pipelines rely on.
AssemblyAI Universal-Streaming takes a different path: partials are emitted in roughly 300ms intervals and are guaranteed immutable once sent. Downstream LLMs can begin processing a partial immediately without waiting for a rewrite. Endpointing fuses acoustic cues, semantic completeness signals, and silence duration, which tends to produce fewer false end-of-turn triggers in semantically complex speech.
The practical integration difference: Deepgram’s evented model requires your orchestration layer to handle EndOfTurn as a discrete signal. AssemblyAI’s immutable partials require your downstream processor to handle a stream of stable chunks rather than a single end-of-turn trigger. Neither is universally better; the right choice depends on how your agent framework dispatches LLM calls.
Beyond turn detection, the feature comparison across the main entrants breaks down as follows:
- Diarization and speaker labeling: — Deepgram and AssemblyAI both support multi-speaker diarization. Gladia includes it for enterprise workflows. Whisper requires third-party tooling (pyannote.audio is the common pairing).
A common gotcha: silence hallucination. Self-hosted Whisper models will generate text on silence segments unless you add a VAD layer (Silero VAD or WebRTC VAD are the standard choices). Managed APIs handle this internally, but behavior varies by model and configuration.
Does fine-tuning or custom vocabulary change which API you should pick?
For most production teams, custom vocabulary and keyword boosting resolve the majority of domain-specific accuracy gaps without the engineering overhead of fine-tuning. Fine-tuning becomes worth the investment when your domain vocabulary is large, highly specialized (medical, legal, financial), and the accuracy delta on entity recognition is measurable in downstream task performance.
- Deepgram: Supports keyword boosting (weighted terms injected at inference time) and custom model fine-tuning via its training API. The Nova-3 model family is the current production-grade option; the legacy Base and Enhanced models remain available but are not the recommended path for new integrations. Model versioning is explicit: Deepgram pins model versions in API requests, so a model upgrade does not break existing integrations without a deliberate version change.
- AssemblyAI: Offers custom vocabulary lists and LeMUR-based prompt customization for post-processing and analytics. Fine-tuning in the traditional sense is not a publicly documented self-serve feature; the primary customization surface is vocabulary and prompt engineering on top of Universal-3 Pro.
- OpenAI Whisper: Full fine-tuning is available because the weights are open-source. This is the highest-control option but requires GPU infrastructure, training data curation, and ongoing maintenance. The engineering cost is non-trivial for teams without existing ML infrastructure.
- Gladia: Supports custom vocabulary for enterprise workflows. Fine-tuning is not a publicly listed self-serve feature.
- OpenTranscription: Routes requests to the model best suited to your cost, accuracy, and latency constraints across 40+ models. Custom vocabulary and model selection are handled at the routing layer, meaning you can switch the underlying model without changing your integration code.
Pro Tip: Before committing to a fine-tuning project, test keyword boosting with a list of 50–100 domain terms. For most use cases, boosting closes 60–80% of the entity-recognition gap at a fraction of the engineering cost. Reserve fine-tuning for cases where boosting plateaus and the accuracy delta has a measurable downstream impact.
Model lifecycle risk is underappreciated. Deepgram’s explicit versioning is a genuine operational advantage: you control when you absorb a model update. AssemblyAI’s Universal family has gone through breaking changes between major versions; pin your model version in production and test upgrades in a staging environment before promoting.
What does pricing actually look like for real workloads?
Per-second billing is now the standard for managed streaming APIs, and it materially reduces cost for short-utterance workloads compared to per-minute billing, which rounds up every sub-60-second segment.
Scenario 1: Live voice agent, 10 concurrent channels, 8 hours/day Assume 8 hours × 10 channels = 80 audio hours per day. At a representative streaming rate (vendor pricing varies and changes; verify current rates directly with each provider), the cost difference between per-second and per-minute billing becomes significant when average utterance length is under 15 seconds. Per-second billing can reduce effective cost by 20–40% for short-utterance conversational workloads versus per-minute rounding.
Scenario 2: Batch transcription, 1,000 audio hours For large batch jobs, Whisper self-hosted on GPU infrastructure (e.g., via Modal or AWS Inferentia) is typically the lowest per-hour cost, but requires infrastructure management, VAD integration, and endpointing engineering. Managed APIs trade higher per-hour cost for zero infrastructure overhead and built-in reliability.
Deployment options by entrant:
- Gladia: — Cloud API with enterprise pipeline integrations. Deployment flexibility details are not publicly listed for self-hosted options.
File size limits also affect media workflows. Providers vary on maximum upload sizes for batch jobs; for large media files (feature-length recordings, multi-hour meetings), verify the provider’s per-file limit before building an ingestion pipeline.
What security and compliance posture should you require from any STT provider?
For enterprise or regulated deployments, the minimum acceptable posture is SOC 2 Type II certification, encryption in transit (TLS 1.2+) and at rest, documented data retention controls, and a clear data processing agreement. HIPAA-eligible deployments additionally require a signed Business Associate Agreement (BAA).
Key items to verify during procurement:
- SOC 2 Type II: Deepgram and AssemblyAI both publish SOC 2 Type II reports; request the current report and note the audit period.
- HIPAA BAA: Available from Deepgram and AssemblyAI under enterprise plans. Confirm scope: does the BAA cover all models and deployment modes you intend to use?
- Data retention: Confirm whether audio and transcript data is retained after processing, for how long, and whether you can opt out of retention entirely. Deepgram’s zero data retention option is available on enterprise plans.
- VPC and private endpoints: Deepgram supports VPC deployment, which keeps audio traffic off the public internet. AssemblyAI’s private deployment is available under enterprise arrangements.
- Encryption at rest: Verify the key management model (provider-managed vs. customer-managed keys).
- SLA uptime commitments: Managed APIs typically publish 99.9% uptime SLAs; confirm whether the SLA covers streaming endpoints specifically, not just the REST API.
Verify that the vendor’s SLA explicitly covers the streaming endpoint you will use in production, not only the batch REST API. Streaming SLAs are sometimes scoped differently and may carry different uptime commitments.
When evaluating a vendor’s security posture, ask specifically: What is the data processing location for audio submitted via the streaming API? Can you provide a network diagram showing where audio is decrypted and processed? What is the incident response SLA for a data breach?
How does developer experience affect time-to-value?
Developer experience often determines time-to-first-transcript more than any accuracy difference. A well-documented SDK with working sample code for your target language can cut integration time from days to hours.
- Gladia: — REST-first API with SDKs for Python and JavaScript. Documentation covers enterprise integration patterns. Community support is less active than Deepgram or AssemblyAI.
- OpenTranscription: Unified API that abstracts model-specific SDKs. Switching the underlying model requires a parameter change, not a code rewrite. The model catalog lists per-model characteristics for direct comparison.
Pro Tip: The fastest way to evaluate developer experience is to run the provider’s streaming demo with a 30-second sample of your actual audio and measure time-to-first-transcript. If the sample app requires more than 15 minutes of setup before you see a transcript, that friction will compound during integration.
Enterprise support tiers vary significantly. Deepgram and AssemblyAI both offer dedicated technical account management under enterprise contracts, with SLA-backed response times for critical issues. Community-tier support for both is primarily async (Discord, GitHub issues, email). For production deployments, confirm whether your plan includes a named TAM and what the P1 response SLA is.
How should you choose between these APIs for your specific project?
Choose by primary constraint, not by feature count. The decision tree is short:
- Real-time feel is the primary requirement (voice agents, live bots): Start with Deepgram Flux for evented turn detection and sub-300ms end-of-turn latency. Evaluate AssemblyAI Universal-Streaming as an alternative if your orchestration layer benefits more from immutable partials than from discrete turn events.
- Integrated audio analytics are required (meeting assistants, call analytics): AssemblyAI’s LeMUR and audio intelligence suite is the more complete offering. Deepgram requires external tooling for sentiment, chapters, and entity detection.
- Cost and data control are the primary constraints: OpenAI Whisper self-hosted is the lowest per-hour cost at scale, but requires VAD, endpointing, and infrastructure engineering. Factor total cost of ownership, not just per-minute API cost.
- Model selection and benchmarking across providers: OpenTranscription routes across 40+ models with real-time ranking, letting you validate which model actually performs best on your audio before committing to a single vendor.
Numbered evaluation checklist:
- Define a representative audio set: 10 samples covering your actual use case (short utterances, noisy telephony, domain vocabulary, overlapping speakers).
- Submit identical samples to each candidate API in the same network region. Measure WER, end-to-end latency, interim stability, and formatting quality.
- Integrate the streaming SDK for your primary language and time the integration. Note any friction points (missing examples, unclear error codes, rate limit behavior).
- Validate security posture: request SOC 2 Type II report, confirm HIPAA BAA availability if required, and verify data retention policy.
- Estimate total cost of ownership for your projected volume, including infrastructure (for self-hosted), support tier, and any enterprise contract minimums.
- Define go/no-go acceptance criteria before the PoC: specific WER threshold, maximum end-of-turn latency, and minimum uptime SLA.
Red flags to watch for:
- Vendor cannot reproduce its published latency claims in your network region during a PoC.
- Interim results rewrite frequently during a single utterance (indicates the model is not streaming-native).
- Data policy does not clearly state whether audio is retained after processing.
- SLA documentation does not explicitly cover the streaming endpoint.
Questions to ask during a PoC: What is the p95 end-of-turn latency on our audio set? How does the model behave on silence segments longer than 2 seconds? What is the upgrade path if a model version is deprecated?
What is the right API for each production use case?
| Use case | Recommended | Primary reason |
|---|---|---|
| Streaming voice agents | Deepgram (Flux) | Evented EndOfTurn, sub-300ms latency |
| Live customer service bots | Deepgram or AssemblyAI | Depends on orchestration model (evented vs. immutable partials) |
| Subtitle and caption workflows | AssemblyAI or Whisper | Accuracy-tuned models; batch-friendly |
| Meeting assistants and analytics | AssemblyAI | LeMUR, sentiment, chapters, entity detection |
| HIPAA-regulated transcription | Deepgram or AssemblyAI | Both offer BAAs; verify scope and deployment mode |
| Model selection and benchmarking | OpenTranscription | 40+ models, real-time ranker, per-second billing |
For voice agents, Deepgram Flux is the default recommendation because evented turn detection reduces false interruptions and integrates cleanly with LLM orchestration frameworks. AssemblyAI is the stronger choice when the downstream system benefits from processing immutable partial transcripts incrementally rather than waiting for a discrete end-of-turn signal.
For analytics-heavy pipelines, AssemblyAI’s integrated audio intelligence suite eliminates the need for separate sentiment, chapter, and entity-detection services, which reduces both integration complexity and per-request latency from chained API calls.
For any team that has not yet committed to a single vendor, OpenTranscription’s real-time ranker provides a live benchmark view across models, so the selection decision rests on measured performance against your audio rather than vendor marketing.
Key Takeaways
For production voice agents, turn-taking latency and interim transcript stability are the decisive selection criteria, not raw WER; Deepgram leads on evented turn detection while AssemblyAI leads on immutable partial stability and integrated audio analytics.
| Point | Details |
|---|---|
| Turn detection is the primary axis | Deepgram Flux emits evented EndOfTurn signals; AssemblyAI Universal-Streaming emits immutable partials. Choose based on your orchestration model. |
| WER leaderboards mislead voice-agent teams | Published accuracy benchmarks measure batch transcription, not end-of-turn latency or interim stability. Run your own PoC on representative audio. |
| Self-hosted Whisper requires engineering overhead | Whisper needs VAD and endpointing logic added before it is viable for live streaming; it remains cost-effective for batch workloads at scale. |
| Compliance requires explicit verification | SOC 2 Type II, HIPAA BAA scope, and data retention policy must be confirmed per deployment mode, not assumed from marketing pages. |
| OpenTranscription benchmarks across 40+ models | Use OpenTranscription to measure which model actually performs best on your audio before committing to a single vendor contract. |
The case for measuring before you commit
The deepgram vs assemblyai debate has a clean surface answer and a messier production reality. Deepgram’s Flux architecture is a genuine advance for voice-agent teams: evented turn detection at sub-300ms median latency is not a marginal improvement over stitched VAD pipelines. But AssemblyAI’s immutable partials solve a different, equally real problem: race conditions between interim rewrites and LLM reasoning are a production failure mode that shows up only after you ship.
What the comparison articles rarely say plainly: the right answer depends on your orchestration architecture, not on which API scores better on a benchmark you did not design. A team building an agent that dispatches LLM calls on discrete turn events will find Deepgram’s model cleaner. A team that processes transcript chunks incrementally as they arrive will find AssemblyAI’s immutability guarantee more valuable.
The practical implication is that you should run a PoC before you commit, and that PoC should use your audio, your network region, and your acceptance criteria. Vendor benchmarks are a starting point, not a procurement decision.
OpenTranscription cuts the time between evaluation and production
Most teams spend weeks running manual comparisons across STT providers, only to discover that the vendor with the best benchmark score underperforms on their specific audio. OpenTranscription routes transcription requests across 40+ models with a real-time ranker, per-second billing, and no subscription lock-in, so you can measure Deepgram, AssemblyAI, Whisper, and others against your actual audio in a single integration.
The platform supports real-time streaming, speaker diarization, 105+ languages, and word-level timestamps with confidence scores. Switching models requires a parameter change, not a code rewrite. For teams that need to validate latency and accuracy before signing an enterprise contract, the model catalog gives you per-model characteristics and live benchmark rankings in one place. Start your evaluation at OpenTranscription and let measured performance drive the decision.
Useful sources
The claims and benchmark methodology in this article draw on the following sources:
- Deepgram vs AssemblyAI vs Whisper: Speech-to-Text for Voice Agents in 2026 — primary source for turn-detection architecture, latency claims, and the practitioner framing of WER vs. turn-taking.
- Deepgram vs. AssemblyAI (2026): Which STT API Should You Choose? (Transcribe Blog) — independent comparison covering deployment options, developer experience, and the speed-vs-accuracy framing.
- Whisper vs Deepgram (Modal) — analysis of self-hosted Whisper trade-offs for batch vs. live streaming workloads.
- Deepgram vs Whisper in 2026 (OpenTypeless) — benchmark methodology guidance: identical audio, same region, unified metrics.
- Speech-to-Text Benchmark: Deepgram vs. Whisper (AIMultiple) — benchmark table covering file size limits and provider variance for media workflows.
- AssemblyAI vs Deepgram (Gladia) — enterprise-oriented comparison with pipeline integration context.
- OpenTranscription Signal blog — model-by-model analysis including Deepgram Flux, Nova-3, and Universal-3 Pro profiles.